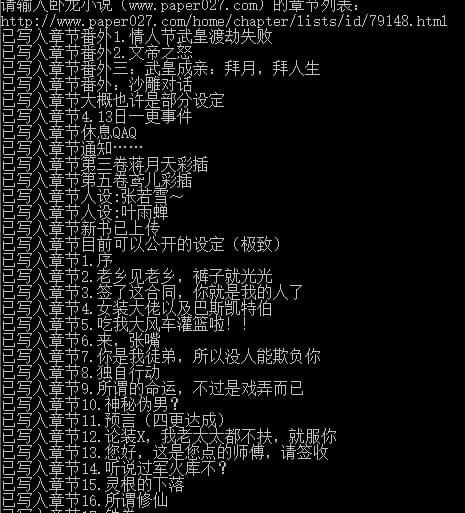
最近在看一部小说,网站随便找的,我设置了1秒间隔,觉得慢可以自己调
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
|
'''
@file :爬卧龙小说.py
@Time :2021-07-21 01:11:43
@Author :Karcyril
@Software :Visual Studio Code
'''
from typing import Container
import requests
from bs4 import BeautifulSoup
import re
import os
import time
import sys
head = {
"User-Agent": "Mozilla/5.0 (Linux; Android 6.0; Nexus 5 Build/MRA58N) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/70.0.3538.25 Mobile Safari/537.36"}
path = sys.argv[0]
filePath = os.path.split(os.path.realpath(__file__))[0]
def main():
baseUrl = input('请输入卧龙小说(www.paper027.com)的章节列表:\n')
getBaseData(baseUrl)
def getBaseData(baseUrl):
ret = requests.request(url=baseUrl, headers=head, method='GET')
soup = BeautifulSoup(ret.text, 'html.parser')
container = soup.select('.container')[2]
tagA = container.select('.chapters span.chapterTitle a')
pLink = re.compile('href="(.*?)"')
pTitle = re.compile('title="(.*?)"')
bookTitle = container.select('div:nth-child(1) a:nth-child(5)')[0].text
with open(filePath+'\\'+bookTitle+'.txt', 'a+')as fp:
fp.write('spider by Karcyril.\n\n')
for link in reversed(tagA):
linkUrl = re.search(pLink, str(link)).group(1)
linkTitle = re.search(pTitle, str(link)).group(1)
getLinkData(linkUrl, linkTitle, bookTitle)
print('完成...')
os.system('pause')
def getLinkData(link, title, bookTitle):
ret = requests.request(url=link, headers=head, method='GET')
soup = BeautifulSoup(ret.text, 'html.parser')
tagPs = soup.select('#contentsource p')
with open(filePath+'\\'+bookTitle+'.txt', 'a+')as fp:
fp.write(title+'\n')
for tagP in tagPs:
with open(filePath+'\\'+bookTitle+'.txt', 'a+')as fp:
fp.write(tagP.text+'\n')
print('已写入章节%s' % (title))
time.sleep(1)
if __name__ == "__main__":
main()
|

 微信