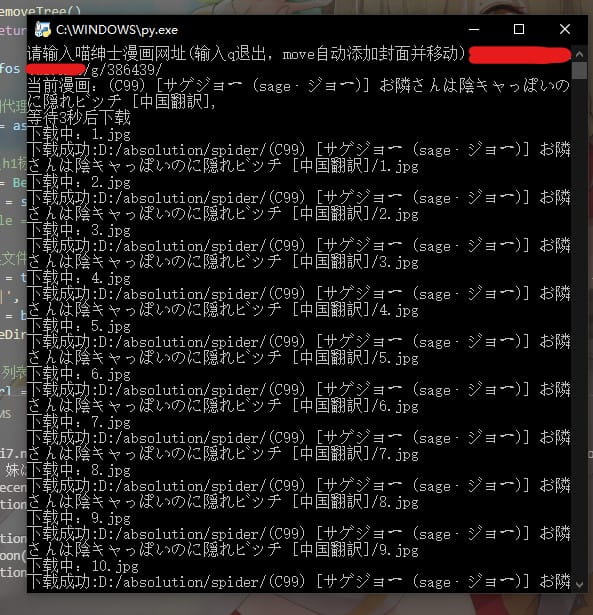
这是新版的,以前的那个网站已经没了。 此网站自带的种子下载几乎没有速度,这个工具可以让你直接从源站下载漫画,我会一边自己用一边完善的
我只提供源码,依赖和开发环境需要你自己准备。。需要科学上网,proxies字段必须填写为你的科学上网工具提供的端口
源码 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 190 191 192 193 194 195 196 197 198 199 200 201 202 203 204 205 206 207 208 209 210 211 212 213 214 215 216 217 218 219 220 221 222 223 224 225 226 227 228 229 230 231 232 233 234 235 236 ''' @file :N站爬虫.py @Time :2022-11-06 22:07:45 @Author :Karcyril @Software :Visual Studio Code ''' import refrom bs4 import BeautifulSoupimport requestsimport osimport shutilfrom multiprocessing import Poolfrom myUtils import askUrl as askUrlimport timefrom requests.exceptions import TimeoutbasePath = '临时目录,用于存放资源' destDir = '路径' proxies = { 'http' : 'http://127.0.0.1:7890/' , 'https' : 'http://127.0.0.1:7890/' } def main (): if os.name == 'nt' : os.system('' ) while (getCartoon(checkUrl(input ('\033[1;36;40m请输入喵绅士漫画网址(输入q退出,move保存并添加封面):\033[0m' )))): pass def getCartoon (articleUrl ): if (articleUrl.upper() == "Q" ): return False if (articleUrl.upper() == "MOVE" ): moveDir() return True if (articleUrl.upper() == "RM" ): removeTree() return True imgInfos = [] resp = askUrl.request(url=articleUrl, proxies=proxies) soup = BeautifulSoup(resp.text, 'html.parser' ) titleElem = soup.select('div#info h2' ) if (titleElem): title = titleElem[0 ].get_text() else : title = soup.select('div#info h1.title' )[0 ].get_text() title = title.replace('<' , '-' ).replace('>' , '-' ).replace('?' , '-' ).replace(':' , '-' ).replace( '|' , '-' ).replace('/' , '-' ).replace('\\' , '-' ).replace('"' , '-' ).replace('*' , '-' ) mPath = basePath+'/' +title createDir(mPath) pageUrl = articleUrl soup = BeautifulSoup(askUrl.request(url=pageUrl).text, 'html.parser' ) imgs = soup.select('div.thumbs div.thumb-container img.lazyload' ) print ('\033[1;33;40m当前漫画:%s,\n等待3秒后下载...\033[0m' % (title)) time.sleep(3 ) resp2 = askUrl.request(url=str (pageUrl)+'/1/' , proxies=proxies) soup2 = BeautifulSoup(resp2.text, 'html.parser' ) downImg = soup2.select('div#content section#image-container img' ) downUrl = re.search('src="(.+//.+/.+/.+/).*"' , str (downImg)).group(1 ) for img in imgs: thumbUrl = re.search('src="(.*?)"' , str (img)).group(1 ) tempName = thumbUrl.split('/' )[-1 ] suffix = tempName.split('.' )[-1 ] count = re.search('(\d+)*.*' , str (tempName)).group(1 ) imgFileName = str (count)+'.' +str (suffix) imgUrl = str (downUrl)+str (count)+'.' +str (suffix) imgInfo = {} imgInfo['url' ] = imgUrl imgInfo['fileName' ] = imgFileName imgInfo['mPath' ] = mPath imgInfos.append(imgInfo) multiGetImg(imgInfo) print ('\033[1;32;40m下载完成...\033[0m\a' ) return True def multiGetImg (imgInfo ): imgUrl = imgInfo['url' ] imgFileName = imgInfo['fileName' ] mPath = imgInfo['mPath' ] print ('下载中:%s' % (imgFileName)) resp = askUrl.request(url=imgUrl) imgData = resp.content with open (mPath+'/' +imgFileName, 'wb+' ) as fp: fp.write(imgData) print ('下载成功:' +mPath+'/' +imgFileName) def createDir (mPath ): if not os.path.exists(mPath): os.makedirs(mPath) def checkUrl (articleUrl ): if (articleUrl[-1 ] == '/' ): articleUrl = articleUrl[:-1 ] return articleUrl def moveDir (): path = basePath listDir = os.listdir(path) haveDup = False for dir in listDir: subDir = path+'/' +dir +'/' files = os.listdir(subDir) haveFolder = False for jpg in files: if (re.match ('Folder.[a-zA-Z]+' , jpg)): haveFolder = True print ('\033[1;31;40m%s文件夹下已经有封面文件了...\033[0m' % (subDir)) break if (haveFolder): continue for jpg in files: if (re.match ('\w+\.(?:[jp][pn]g|webp)' , jpg, re.I)): firstImg = subDir+jpg coverImg = subDir+'Folder.' +jpg.split('.' )[-1 ] with open (firstImg, 'rb+' ) as oFp, open (coverImg, 'wb+' ) as nFp: imgData = oFp.read(-1 ) nFp.write(imgData) break if (not isDupDir(dir , destDir)): shutil.move(subDir, destDir) print ('\033[1;32;40m移动完成:<%s>\033[0m' % (dir )) else : print ( '\033[1;31;40m\n********************\n警告!此文件夹已存在:<%s>\n********************\n\033[0m' % (dir )) haveDup = True if not haveDup: removeTree() def isDupDir (src, dest ): dirs = os.listdir(dest) for dir in dirs: if (src == dir ): return True return False def removeTree (): shutil.rmtree(basePath) if __name__ == "__main__" : main()

 微信