在wp中获取元数据的方法:get_post_meta() ,该方法返回一个数组
测试demo:
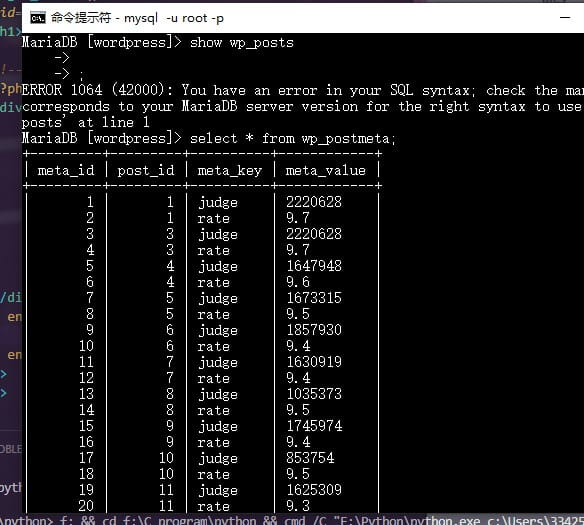
爬取网页获取元数据,并将其插入到wp_postmeta中,使用cur.lastrowid属性获取最后一个插入的数据ID, 必须是AUTO_INCREMENT才行
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
|
'''
@文件 :spider.py
@时间 :2020-12-25 15:10:45
@作者 :Karcyril
'''
import urllib.request
import urllib.parse
import urllib.error
from bs4 import BeautifulSoup
import pymysql
import re
pLink = re.compile(r'<a href="(.*)".*>')
pTitle = re.compile(r'<span class="title">(.*?)</span>')
pBd = re.compile(r'<p class=.*?>(.*?)</p>', re.S)
pJudge = re.compile(r'<span>(\d*)人评价</span>')
pRate = re.compile(r'<span class="rating_num".*?(\d*.?\d?)</span>')
def main():
baseUrl = 'https://movie.douban.com/top250?start='
getData(baseUrl)
def getData(baseUrl):
dataList = []
conn = pymysql.connect('localhost', 'root', '123456', 'database')
cur = conn.cursor()
for i in range(0, 1):
html = askURL(baseUrl+str(0*25))
bs = BeautifulSoup(html, 'html.parser')
for item in bs.find_all('div', class_='item'):
strItem = str(item)
mLinks = pLink.findall(strItem)[0]
mZHTitle = pTitle.findall(strItem)[0]
if(len(pTitle.findall(strItem)) > 1):
mZHTitle += pTitle.findall(strItem)[1]
mBd = pBd.findall(strItem)[0]
mJudge = pJudge.findall(strItem)[0]
mRate = pRate.findall(strItem)[0]
sql = r'INSERT INTO wp_posts (post_author,post_title,post_content) VALUES ("btkrc","%s","%s");' % (
mZHTitle, mBd)
cur.execute(sql)
id = cur.lastrowid
cur.execute(insertPostMetaSql(str(id), 'judge', mJudge))
cur.execute(insertPostMetaSql(str(id), 'rate', mRate))
conn.commit()
cur.close()
conn.close()
def insertPostMetaSql(postId, metaKey, metaValue):
sql = r'INSERT INTO wp_postmeta (post_id,meta_key,meta_value) VALUES("%s","%s","%s");' % (
postId, metaKey, metaValue)
return sql
def askURL(baseUrl):
head = {
"User-Agent": "Mozilla/5.0 (Linux; Android 6.0; Nexus 5 Build/MRA58N) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/70.0.3538.25 Mobile Safari/537.36"}
res = urllib.request.Request(url=baseUrl, headers=head)
html = ""
try:
response = urllib.request.urlopen(res)
html = response.read().decode('utf-8')
except urllib.error.URLError as e:
if hasattr(e, "code"):
print(e.code)
if hasattr(e, 'reason'):
print(e.reason)
return html
if __name__ == "__main__":
main()
|
结果如下:
wp代码:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
| <?php get_header(); ?>
<div id="header">
<h1><a href="#"><?php bloginfo('name'); ?></a></h1>
<!-- post主循环 -->
<?php if (have_posts()) : ?><?php while (have_posts()) : the_post(); ?>
<div class="post">
<h2><a href="<?php the_permalink() ?>"><?php the_title() ?></a></h2>
<div class="entry">
<?php the_content(); ?>
<p class="postmetadata">
<!-- 参数为分隔符 -->
<?php echo "当前评分人数:" . get_post_meta(get_the_ID(), "judge")[0]; ?>
<?php echo "分数:" . get_post_meta(get_the_ID(), "rate")[0]; ?>
</p>
</div>
</div>
<?php endwhile; ?>
<?php endif; ?>
</div>
</div>
<?php get_sidebar(); ?>
<?php get_footer(); ?>
|
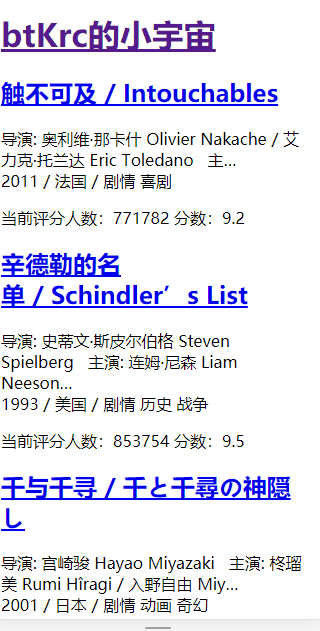
最终效果如下

 微信