域名更换之后不用管,直接把漫画页面整个url复制上去就行了
2021-11-18
这个网站服务器在国外,经常间歇性宕机,所以我没有限制重试次数,一直请求直到获取数据。
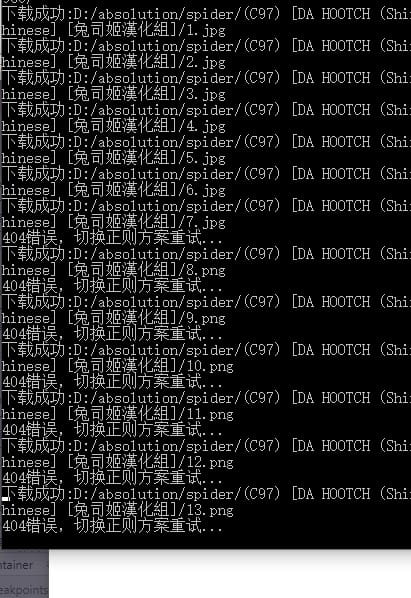
有少数漫画会放一些虚假的标签上去,直接爬会得到一堆404。
真正的url隐藏在js脚本里(也可能会失效),img标签里的url真假混合在一起,所以必须每次都进行状态码判断
由于我需求量不大暂时没有添加多线程(协程)
更新日志 2021-03-09 20:05:45 可能报错522导致程序异常中止,修复了一下
myUtils.py
1
2
3
4
except requests.exceptions.HTTPError as err: print ('错误码:%d\n' % (err.response.status_code)) if (err.response.status_code == 404 ): return err.response
spider.py
主循环修改如下:
1 2 3 4 5 6 7 8 if (resp.status_code == 404 ): imgUrl = re.search( 'onerror="javascript:this.src=\'(.*?)\'.*?"' , str (img)).group(1 ) resp = askUrl.request(url=imgUrl) if (resp.status_code == 404 ): return
源码 askUrl源码在这里
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 190 191 192 193 194 195 196 197 198 ''' @file :爬喵绅士.py @Time :2021-12-18 12:28:15 @Author :Karcyril @Software :Visual Studio Code ''' import refrom bs4 import BeautifulSoupimport requestsimport osimport shutilfrom multiprocessing import Poolfrom myUtils import askUrl as askUrlfrom requests.exceptions import TimeoutbasePath = 'your directory' destDir = 'your directory' def main (): while (getCartoon(checkUrl(input ('请输入喵绅士漫画网址(输入q退出,move自动添加封面并移动):' )))): pass def getCartoon (articleUrl ): if (articleUrl.upper() == "Q" ): return False if (articleUrl.upper() == "MOVE" ): moveDir() return True if (articleUrl.upper() == "RM" ): removeTree() return True imgInfos = [] resp = askUrl.request(url=articleUrl) soup = BeautifulSoup(resp.text, 'html.parser' ) title = soup.select('div#info h1' )[0 ].get_text() title = title.replace('<' , '-' ).replace('>' , '-' ).replace('?' , '-' ).replace(':' , '-' ).replace( '|' , '-' ).replace('/' , '-' ).replace('\\' , '-' ).replace('"' , '-' ).replace('*' , '-' ) mPath = basePath+'/' +title createDir(mPath) pageUrl = articleUrl+'/list2/' soup = BeautifulSoup(askUrl.request(url=pageUrl).text, 'html.parser' ) imgs = soup.select('section#image-container img.list-img.lazyload' ) for img in imgs: imgUrl = re.search('data-src="(.*?)"' , str (img)).group(1 ) imgFileName = imgUrl.split('/' )[-1 ] imgInfo = {} imgInfo['url' ] = imgUrl imgInfo['fileName' ] = imgFileName imgInfo['mPath' ] = mPath imgInfo['img' ] = img imgInfos.append(imgInfo) multiGetImg(imgInfo) print ('下载完成...\a' ) return True def multiGetImg (imgInfo ): imgUrl = imgInfo['url' ] imgFileName = imgInfo['fileName' ] mPath = imgInfo['mPath' ] img = imgInfo['img' ] print ('下载中:%s' % (imgFileName)) resp = askUrl.request(url=imgUrl) if (resp.status_code == 404 ): imgUrl = re.search( 'onerror="javascript:this.src=\'(.*?)\'.*?"' , str (img)).group(1 ) resp = askUrl.request(url=imgUrl) if (resp.status_code == 404 ): return imgData = resp.content with open (mPath+'/' +imgFileName, 'wb+' ) as fp: fp.write(imgData) print ('下载成功:' +mPath+'/' +imgFileName) def createDir (mPath ): if not os.path.exists(mPath): os.makedirs(mPath) def checkUrl (articleUrl ): if (articleUrl[-1 ] == '/' ): articleUrl = articleUrl[:-1 ] return articleUrl def moveDir (): path = basePath listDir = os.listdir(path) haveDup = False for dir in listDir: subDir = path+'/' +dir +'/' files = os.listdir(subDir) haveFolder = False for jpg in files: if (re.match ('Folder.[a-zA-Z]+' , jpg)): haveFolder = True print ('%s文件夹下已经有封面文件了...' % (subDir)) break if (haveFolder): continue for jpg in files: if (re.match ('\w+\.(?:[jp][pn]g|webp)' , jpg, re.I)): firstImg = subDir+jpg coverImg = subDir+'Folder.' +jpg.split('.' )[-1 ] with open (firstImg, 'rb+' ) as oFp, open (coverImg, 'wb+' ) as nFp: imgData = oFp.read(-1 ) nFp.write(imgData) break if (not isDupDir(dir , destDir)): shutil.move(subDir, destDir) print ('移动完成:%s' % (dir )) else : print ('警告!此文件夹已存在:%s' % (dir )) haveDup = True if not haveDup: removeTree() def isDupDir (src, dest ): dirs = os.listdir(dest) for dir in dirs: if (src == dir ): return True return False def removeTree (): shutil.rmtree(basePath) if __name__ == "__main__" : main()

 微信